Project Details
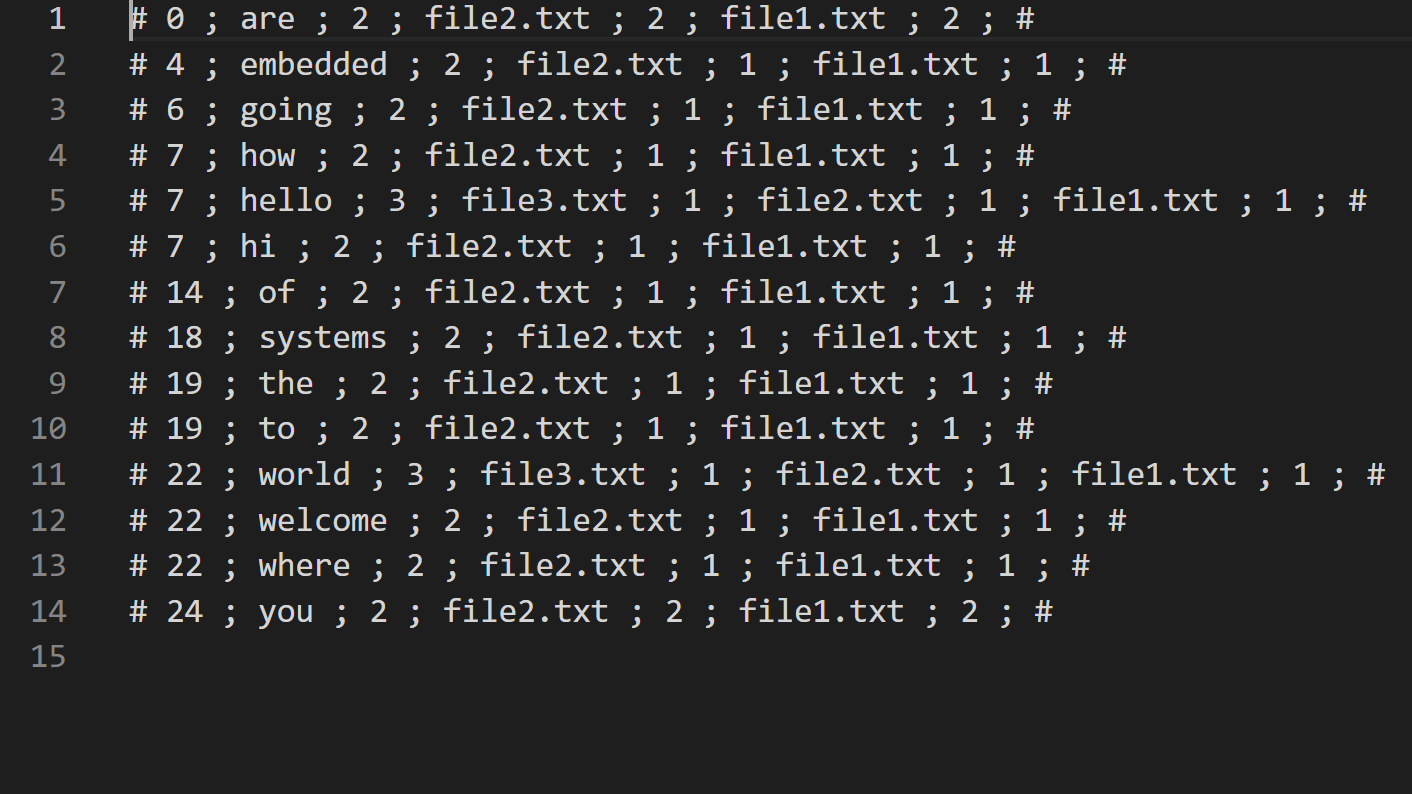
Project information
- Name: Inverted Search
- Category: Command line Application program
- Language: C
- Project URL: Inverted Search
Inverted Search - A command line application program
A C-based command-line application that implements an inverted search engine to efficiently index and retrieve words from multiple text files. It constructs an inverted index using hash tables and linked lists, mapping each unique word to the files and frequencies in which it appears. The project demonstrates strong proficiency in file handling, data structures, dynamic memory management, and efficient search algorithms at a low-level system design scale.
Development Highlights
Features implemented:
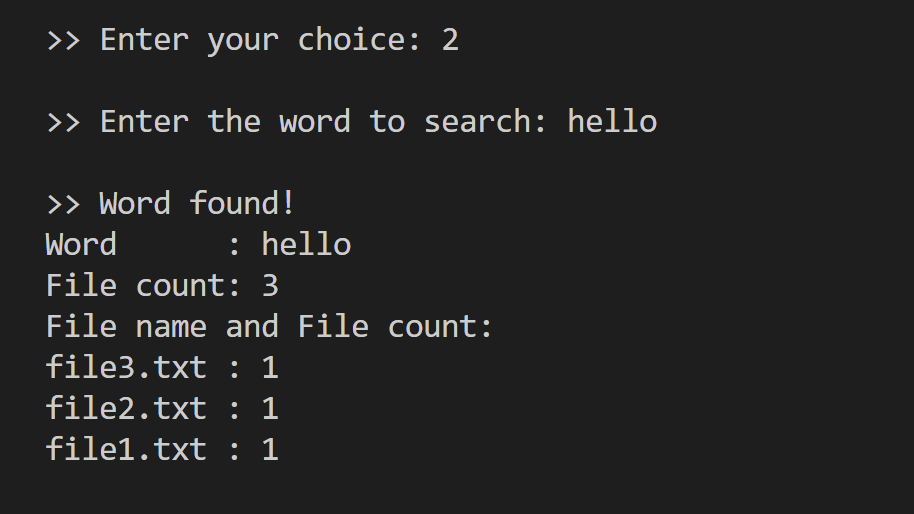
- 🔍 Inverted Search Engine – Efficiently searches words across multiple text files using an inverted index technique
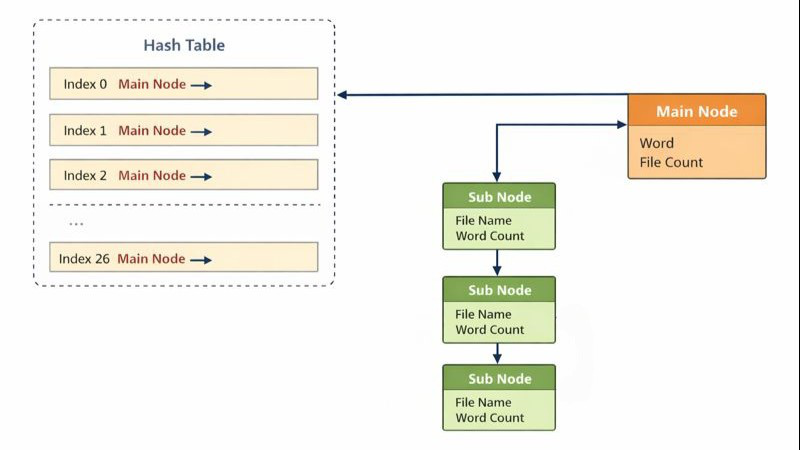
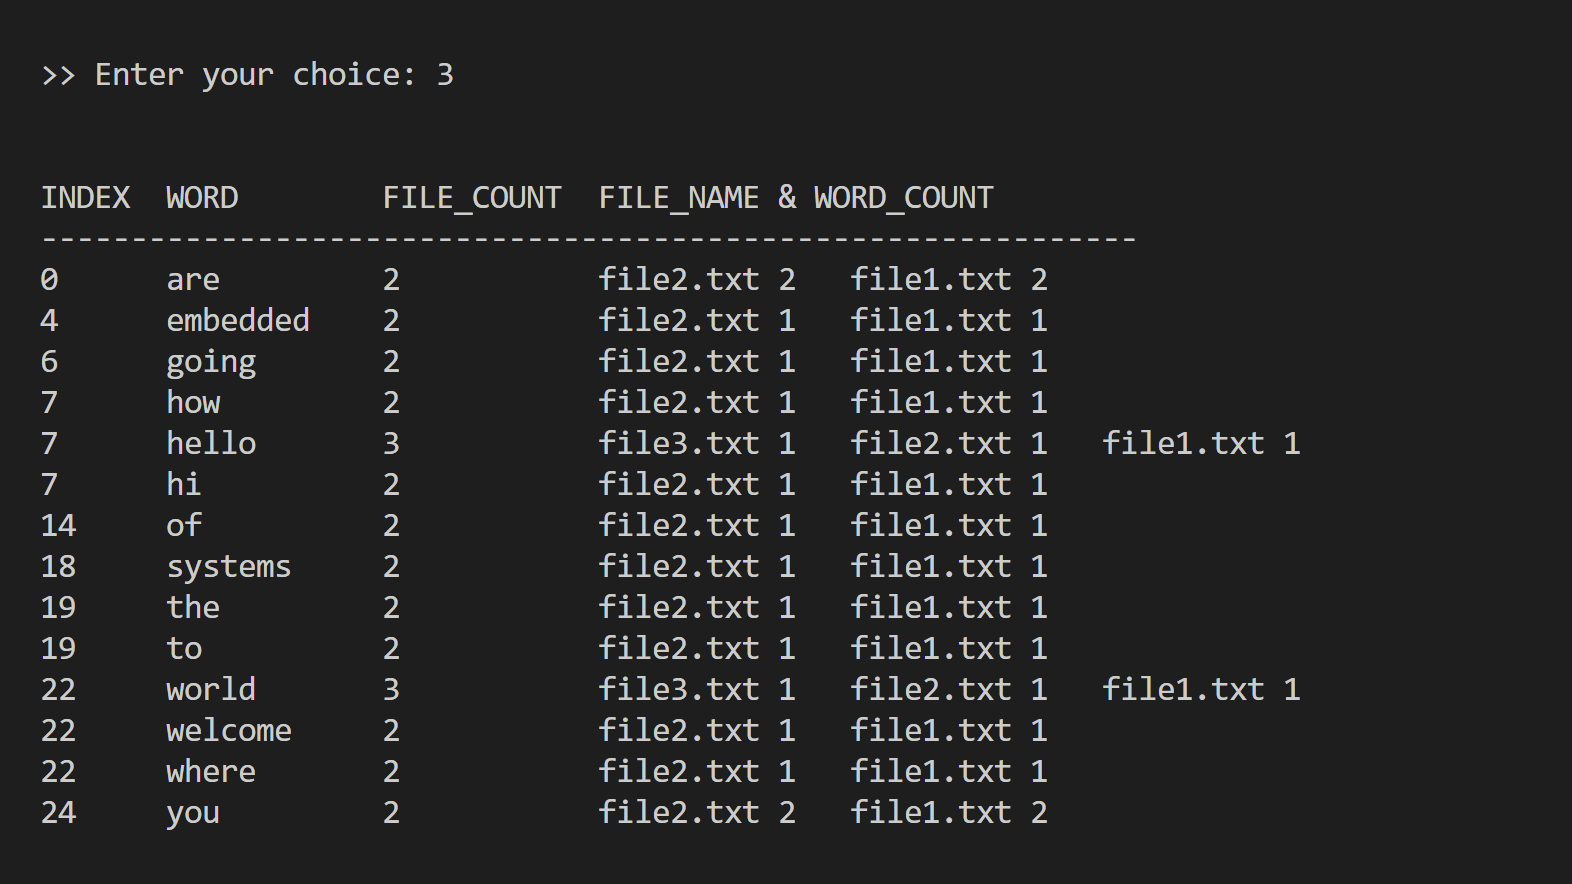
- 📚 Inverted Index Construction – Maps each unique word to the list of files and occurrence counts where it appears
- 🗂 Multi-File Processing – Reads and processes multiple input text files provided via command-line arguments
- 🧠 Tokenization & Normalization – Extracts words by filtering special characters and handling case sensitivity
- ⚙️ Hash Table Based Storage – Uses a hash table to store words for fast insertion and lookup operations
- 🔗 Linked List Chaining – Resolves hash collisions using linked lists for scalable word storage
- 📊 Word Frequency Tracking – Maintains occurrence count of each word per file
- 🚫 Duplicate File Handling – Prevents re-processing of the same file multiple times
- 🧱 Modular Design – Clean separation of logic using source and header files for indexing, searching, and utilities
- 🚨 Robust Error Handling – Detects invalid files, empty files, duplicate inputs, and incorrect arguments gracefully
- 💾 Dynamic Memory Management – Allocates and frees memory safely to avoid memory leaks
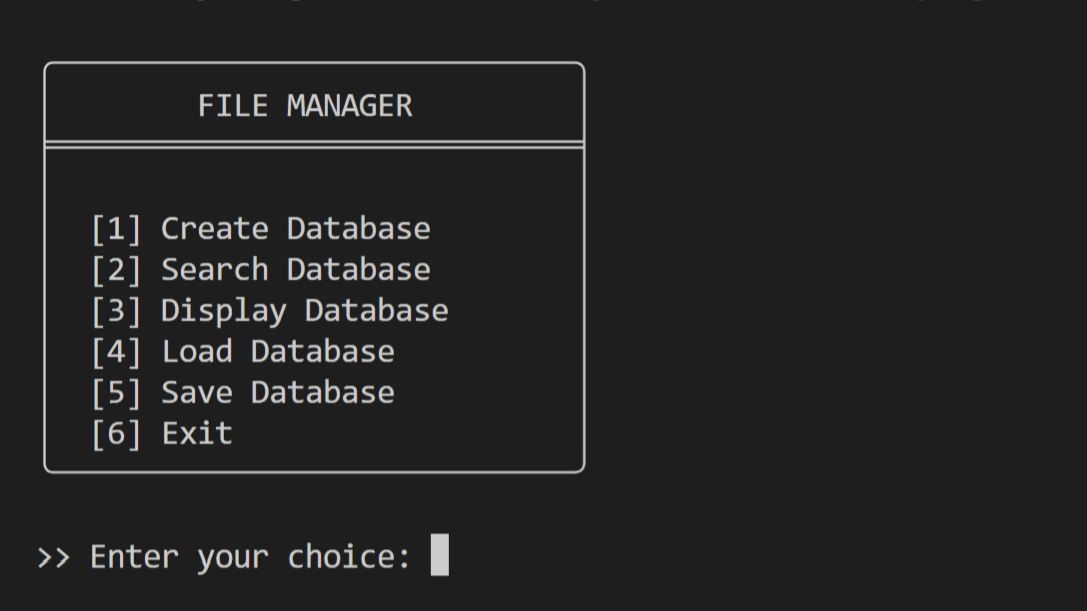
- 💻 Command-Line Interface – Simple and efficient CLI for database creation, search, display, and save operations